While AI models can break down problems into structured steps, new research reveals they still fail at basic arithmetic and fact-checking—raising questions about their true reasoning abilities.
Large Language Models (LLMs) have become indispensable in natural language processing, excelling at tasks such as sentiment analysis, reading comprehension, and answering factual questions. However, their ability to perform complex, multi-step reasoning remains a significant challenge, particularly in question-answering tasks that demand logical inference rather than simple recall. This study, authored by Nick Ferguson, Liane Guillou, Alan Bundy, and Kwabena Nuamah from the University of Edinburgh and Aveni, examines the extent to which LLMs can engage in two distinct forms of reasoning: meta-level and object-level reasoning.
Understanding Meta-Level and Object-Level Reasoning
Meta-level reasoning involves high-level strategic thinking, including problem decomposition and the formulation of intermediate steps necessary to solve a question. Object-level reasoning, in contrast, refers to the execution of these steps, such as performing mathematical calculations, retrieving specific facts, or applying symbolic logic. To evaluate the capabilities of LLMs in these areas, the authors introduce FRANKLIN, a novel dataset that explicitly requires models to engage in both reasoning types. FRANKLIN is inspired by the FRANK system, a symbolic reasoning framework for question answering, and focuses on geopolitical indicators such as population trends, economic metrics, and regional comparisons. Alongside three established multi-step question-answering datasets, FRANKLIN serves as a benchmark for testing the performance of four specific LLM versions: Meta’s Llama 3.1 8B, Microsoft’s Phi 3.5 Mini, Google’s Gemma 2 9B, and OpenAI’s GPT-4o-mini. Through two human annotation studies, the researchers assess whether LLMs can successfully generate reasoned responses and whether prompting them to plan their answers before execution improves their performance.
How LLMs Approach Reasoning Tasks
The study situates its analysis within the broader context of LLM reasoning tasks. As a cognitive function, reasoning encompasses logical deduction, belief revision, and inference-making. Common sense reasoning requires an understanding of everyday concepts and the ability to infer implicit knowledge. Mathematical reasoning demands numerical operations and logical problem-solving, while symbolic reasoning involves rule-based manipulations, such as emulating formal logic or deducing relationships between abstract entities. Multi-step reasoning is particularly significant, as it necessitates the sequential application of inference processes to arrive at a final answer. Despite their advancements, LLMs often struggle with these tasks because they rely on statistical pattern-matching rather than genuine logical deduction.
Existing techniques attempt to improve LLM performance on reasoning tasks. Fine-tuning involves additional training on domain-specific datasets to enhance accuracy in particular tasks while prompting techniques such as Chain-of-Thought (CoT) to introduce explicit reasoning steps into model responses. These approaches have demonstrated improvements, yet doubts remain as to whether LLMs are genuinely reasoning or merely imitating structured thought patterns learned from their training data. The authors propose a more structured classification of LLM reasoning, distinguishing between meta-level and object-level processes. While meta-level reasoning involves planning, selecting relevant knowledge sources, and determining the steps required to solve a problem, object-level reasoning focuses on accurate execution, including factual retrieval, numerical precision, and logical deductions.
FRANKLIN Dataset: A New Challenge for LLMs
To assess these reasoning types, the study introduces the FRANKLIN dataset, inspired by the FRANK system, which employs explicit symbolic reasoning to solve complex questions. FRANKLIN consists of complex questions requiring both meta- and object-level reasoning, particularly in the domain of geopolitical indicators. It includes scenarios requiring future prediction, regional comparisons, historical trends, and projections. Unlike more straightforward fact-retrieval datasets, FRANKLIN forces LLMs to not only determine the correct problem-solving approach but also accurately retrieve and manipulate relevant data. Each question is paired with a detailed explanation outlining the necessary reasoning steps. This dataset poses a significant challenge for LLMs, as it requires them not only to determine the appropriate strategy for answering a question but also to accurately retrieve and manipulate data.
How LLMs Were Evaluated: Two Human Annotation Studies
The evaluation design consists of two human annotation studies. In the first, LLMs were prompted to directly answer questions, allowing assessment of their object-level reasoning abilities. In the second, models were first asked to generate a plan before executing their reasoning steps, testing their meta-level reasoning skills. Participants rated responses based on their coherence, correctness, and the presence of structured reasoning. The study also introduced three key evaluation metrics:
- Answer Failure Rate (AFR) – the percentage of cases where an LLM provided no attempted answer.
- Rational Approach Rate (RAR) – the proportion of responses that outlined a coherent problem-solving approach.
- Plan Creation Rate (PCR) – the percentage of responses that structured their reasoning in a clear, step-by-step manner.
The results reveal a clear divergence in LLM performance between these two reasoning levels.
Key Findings: Meta-Level Strength, Object-Level Weakness
Across all datasets, LLMs consistently demonstrated strong meta-level reasoning. Responses often contained structured, step-by-step explanations that human annotators rated as rational and interpretable. Even for complex questions in FRANKLIN, models exhibited an ability to break down problems into intermediate steps and articulate a plan for solving them. However, while these responses appeared structured, the study raises concerns about whether they represent true reasoning or simply an imitation of learned patterns.
In contrast, LLMs struggled significantly with object-level reasoning. Object-level reasoning failures were frequent, particularly when questions required numerical precision or factual recall. In FRANKLIN, for example, models frequently fabricated numerical data, provided incorrect values, or made basic arithmetic errors. Even when models successfully identified the correct reasoning path, they often failed to follow through with accurate computations or fact retrieval. Error patterns included:
- Fabricating numerical data (e.g., citing non-existent sources).
- Retrieving inaccurate or imprecise information (e.g., rounding values incorrectly).
- Performing incorrect calculations (even for simple arithmetic operations).
A closer analysis of errors highlights the nature of these failures. Some responses contained entirely fabricated data, where models cited non-existent sources or invented statistical figures. Others retrieved information with reduced precision, rounding values or omitting key details necessary for accurate comparisons. In mathematical tasks, models often produce incorrect calculations, even for simple operations. These findings suggest that while LLMs can structure their responses in a way that appears logical, they lack the robust execution skills necessary to reliably generate correct answers in domains requiring object-level reasoning.
Implications for LLM Development
The findings have significant implications for the development of LLMs. While prompting models to engage in meta-level reasoning improves their ability to articulate coherent strategies, it does not address their deficiencies in object-level reasoning. This suggests that future advancements must focus on integrating external symbolic reasoning components, improving factual retrieval mechanisms, and refining numerical processing capabilities. The FRANKLIN dataset serves as a critical benchmark, demonstrating that even models with strong problem-decomposition skills struggle with execution.
Conclusion: The Path Forward for AI Reasoning
In conclusion, the study highlights a critical distinction in the reasoning capabilities of LLMs. While they can effectively plan and structure problem-solving approaches, their ability to execute complex reasoning tasks remains limited. The study’s findings emphasize that LLMs are proficient at mimicking reasoning structures but not necessarily reasoning in a human-like, cognitive sense. The introduction of FRANKLIN offers a new means of evaluating these deficiencies, laying the groundwork for further research into improving LLM performance in multi-step question answering. The results underscore the need for continued refinement in how LLMs handle object-level reasoning, ensuring that future iterations can move beyond surface-level imitation and towards genuine cognitive reasoning abilities.
- Preliminary scientific report. Ferguson, N., Guillou, L., Bundy, A., & Nuamah, K. (2025). Evaluating the Meta- and Object-Level Reasoning of Large Language Models for Question Answering. ArXiv. https://arxiv.org/abs/2502.10338

News
Our books are available worldwide!
Online Sellers other than Amazon, Routledge, and IOPP Indigo Global Health Care Equivalency in the Age of Nanotechnology, Nanomedicine and Artifcial Intelligence Global Health Care Equivalency In The Age Of Nanotechnology, Nanomedicine And Artificial [...]
Scientists Discover a Surprising New Power of Honey That Could Protect Your Skin
Honey’s medical uses may go beyond healing wounds, as laboratory experiments suggest multifloral honey could strengthen human skin cells’ defenses against damaging UV radiation. Ultraviolet (UV) radiation from sunlight can accelerate skin aging and [...]
Scientists Discover That Male and Female Hearts Age in Surprisingly Different Ways
A new study reveals surprising differences in how male and female hearts age at the cellular level. The heart may age very differently from one region to another. A detailed study of mouse hearts [...]
An Ancient Virus May Hold the Secret to What Makes the Human Brain Different
Could a virus that infected chimpanzees millions of years ago help explain how the human brain became different? Researchers at Lund University have discovered that ancient viral DNA embedded in the chimpanzee genome silences [...]
Could a Nasal Spray Stop Alzheimer’s Before Memory Loss Begins?
Protecting memory from Alzheimer’s may one day involve a nasal spray, with encouraging results in animals and evidence that its particles also protect human neurons grown in the lab. Alzheimer’s disease damages the connections [...]
A sceptical guide to AI agents in drug discovery
In conversation with Dr Eric Ma, Senior Principal Data Scientist at Moderna, Dr Raminderpal Singh examines what AI agents are actually good for, where the lock-in hides and why expertise has become more valuable [...]
Study identifies new targets for antiviral drugs against coronaviruses
A study led by researchers at the University of California San Diego School of Medicine and University of California, Riverside (UCR) School of Medicine has identified new targets for antiviral drugs against coronaviruses, including [...]
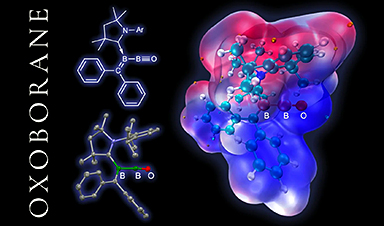
“Nearly Everybody Had Given Up” – Scientists Finally Solve a 60-Year Chemistry Mystery
After more than six decades of failed attempts, chemists have achieved a breakthrough involving a class of molecules long considered too unstable to isolate. Chemists have succeeded in isolating a group of molecules that [...]
Depression Symptoms Improved in Just 48 Hours After a Single Psychedelic Dose
A single dose of psilocybin produced rapid antidepressant effects in a small Swedish clinical trial, with improvements lasting for weeks. A single dose of psilocybin, the psychedelic compound found in magic mushrooms, produced rapid [...]
GHCE Concept
From the preface of the book Global Health Care Equivalency in the Age of Nanotechnology, Nanomedicine and Artificial Intelligence, Edited by Frank Boehm: Since the publication of my first book (Nanomedical Device and Systems [...]
Human Bodies Are Producing Two Billion Tons of CO2 a Year
A new study reveals that the amount of carbon dioxide produced by human metabolism has increased dramatically over three decades. The carbon dioxide produced by human bodies as they convert food into energy increased [...]
A Hidden DNA Mechanism Could Explain How 20% of Human Cancers Develop
Researchers have identified an unexpected molecular vulnerability in cancers carrying BAF mutations. Mutations found in roughly 20% of human cancers may promote tumor growth by changing how DNA is organized inside cells. Researchers have [...]
Ebola kills over 5,300 in fastest-growing outbreak on record
Africa’s latest Ebola outbreak has killed nearly 5,400 people, the vast majority of them in the Democratic Republic of Congo (DRC), according to the continent’s top health agency. Africa Centres for Disease Control and [...]
China makes early progress in using sound waves to stimulate damaged brains
Chinese researchers are testing whether focused ultrasound can help restore consciousness in patients with severe brain injuries, adding to a growing international effort to use sound waves to stimulate deep brain structures without surgery. [...]
Micro-drones fly through the body thanks to ultrasound
At the EPFL, micro-drones have been developed that can be moved without a motor or battery.No motors, no batteries, no electronics on board, just small cavities that convert sound waves into thrust: this is [...]
A Single Enzyme Could Hold the Key to Treating a Devastating Brain Disorder
Blocking an enzyme’s production restored brain growth and healthy behaviors in mice engineered to develop Angelman syndrome, pointing to a possible treatment target. Children with Angelman syndrome begin to show difficulties with thinking and [...]